Assessing Service Virtualization Tools for Cloud Native Architectures
| Shelf | AI & ML |
|---|---|
| Date in | |
| Readers | 567 |
Service virtualization tools must adapt to the dynamic needs of cloud native architectures, focusing on accuracy, deployment independence, and real-time configuration updates.
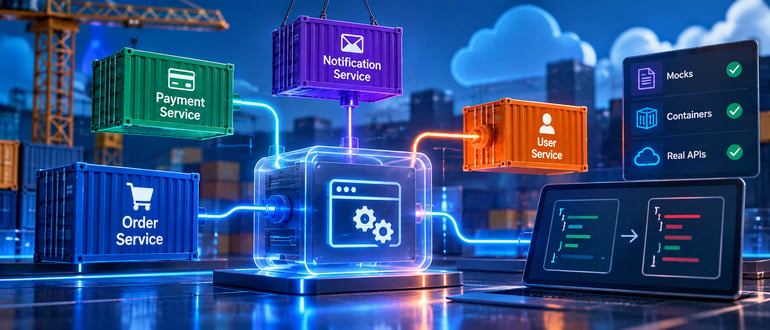
Service virtualization has become a critical aspect in modern software development, especially as organizations transition toward cloud native architectures. This shift demands more from virtualization tools than was previously necessary. Traditionally developed tools fall short in environments characterized by rapid, independent service deployments, which can alter behaviors unexpectedly.
Understanding the Shift to Cloud Native
Previous service virtualization tools were designed for environments where services had predictable deployment schedules, allowing teams to anticipate changes in service behavior. With cloud native architectures, however, the landscape shifts dramatically. Services now deploy independently and continuously, making it essential for virtualization tools to evolve accordingly. A payment service, for instance, can undergo multiple deployments in a single day, potentially affecting how downstream services interact with it without prior notice.
This independent deployment inherent in cloud native environments creates a risk of configuration drift—where virtual service representations become misaligned with the actual state of deployed services. Such discrepancies can lead to failures in integration tests, as outdated configurations lead to misleading validation results.
Independent Deployment: A New Normal
The very principle of independent deployment necessitates a rethink of how service virtualization tools manage configurations. Unlike prior models where everything was synchronized, the differential rate of deployments now means that configurations need to be dynamically updated. Without mechanisms to automatically refresh these configurations, tools leave downstream teams stranded with outdated information, leading to increased integration testing ambiguity.
The challenge extends far beyond just configuration management; it's about maintaining accuracy in the face of constantly changing upstream services. A tool needs to evolve from simply creating virtual services to incorporating mechanisms that keep those configurations in sync with the rapidly altering upstream services.
Configuration Accuracy: Varieties of Tools
Addressing configuration accuracy requires an understanding of the various approaches different tools take: observation-based, specification-based, and container-based.
Observation-Based Tools
These tools create virtual service configurations by capturing real traffic during controlled scenarios. For example, Keploy utilizes eBPF for real-time traffic observation across various languages and frameworks. The strength of observation-based tools lies in their ability to automatically refresh configurations after each deployment. By re-recording service interactions post-deployment, they can detect and reflect any behavioral changes, obviating the need for manual updates to the virtual service configuration.
This automation shifts the maintenance burden from developers to the deployment cycle, significantly reducing the risk of outdated test responses and improving reliability in testing.
Specification-Based Tools
On the other hand, specification-based tools derive their configurations from documented API contracts and manually generated mapping files, like those seen with WireMock and Pact. While these tools ensure accuracy based on their defined specifications, they face limitations when upstream services evolve without corresponding updates in the specifications. If an API field changes without adjusting the mapping files, the virtual service can return incorrect or incomplete responses, generating false positives in testing scenarios.
Container-Based Tools
Container-based tools, such as Testcontainers, run actual service instances in isolated environments, providing fidelity that virtual services cannot match. They are particularly beneficial when the semantic integrity of services is crucial, such as for testing database constraints or messaging guarantees. However, their use is limited by the need to have the real service software available for execution, which may not always be feasible.
Challenges with Language Diversity
Another critical aspect of cloud native architectures is their polyglot nature, with diverse services often built in different programming languages. Traditional virtualization tools may struggle here, as configurations often need to be tailored to specific languages and frameworks. This not only increases complexity but can also lead to inconsistencies across services that utilize the same upstream dependencies.
Tools that focus on network-level interactions can eliminate this concern by intercepting traffic irrespective of the application language, allowing a unified virtual service configuration to be utilized across various testing environments.
The Need for Diff Visibility
Clarity around changes in service behavior post-deployment is essential for teams to adapt downstream applications accordingly. Service virtualization tools that highlight differences between previous and new configurations following a refresh process empower teams to make informed decisions. In the absence of explicit differentiation, teams risk adopting configurations without fully understanding potential impacts, potentially leading to further complications in later integration tests.
Tailoring Tools to Requirements
Selecting the appropriate service virtualization tool depends on the specific needs of a cloud native architecture. If both teams are responsible for maintaining API contracts, specification-based tools could offer strong accuracy in contract verification, helping to sustain behavioral consistency. For organizations with numerous independent upstream service deployments or third-party APIs, observation-based tools provide a more direct approach to managing configuration integrity without manual intervention.
Meanwhile, for scenarios where real infrastructure behaviors are fundamental to testing, container-based tools may represent the best option, allowing simulations with high fidelity.
A Comprehensive Approach
Cloud native environments often comprise a mix of internal APIs, third-party integrations, and infrastructure dependencies. The most effective service virtualization strategy will involve a combination of tool types that address each dependency’s unique requirements. By leveraging the right mix—observation, specification, and containerization—organizations can maintain configuration relevancy and testing accuracy as their architectural complexities grow.
Ultimately, navigating the intricacies of service virtualization in a cloud native architecture means understanding the evolving landscape and selecting tools that keep pace with independent deployment patterns, ensuring that testing remains reliable and reflective of the actual services in use.